What the study tested
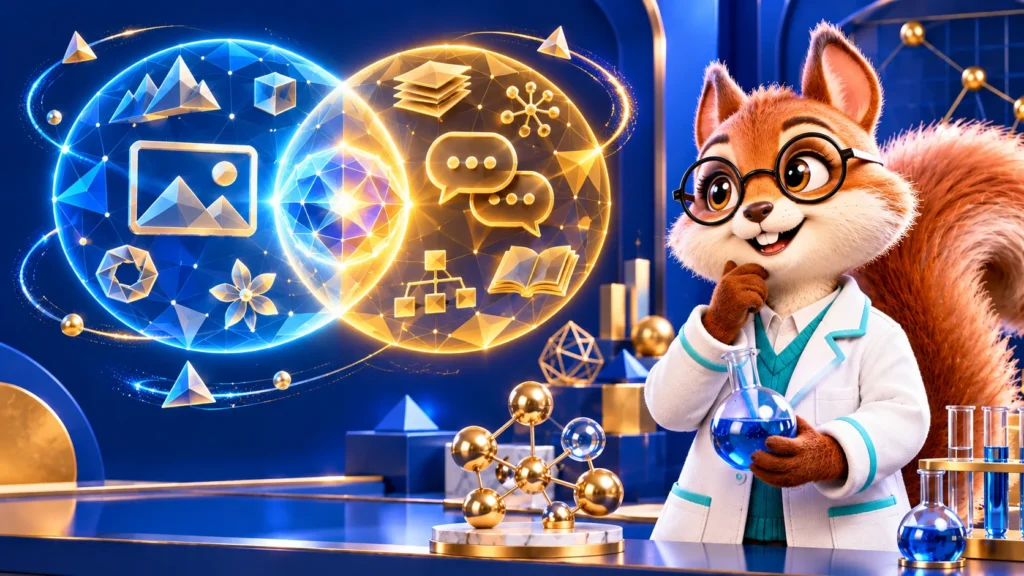
A photograph of a cat and a sentence about that cat look nothing alike. Yet they can describe the same scene. Could AI systems trained on different kinds of information develop similar internal maps of it?
A preprint by Randall Balestriero and Yann LeCun explores this question using an approach called JEPA. A preprint is a research paper shared before completed peer review should be assumed. The authors present a mathematical result under stated assumptions and experiments on how different representations can align.
Their key idea is that two descriptions can be useful “views” of the same scene. In one comparison on the same corpus, a JEPA trained with such views reached a similar alignment level after 21.6 million training samples; next-token prediction reached it after 900 million. The authors describe that as approximately 42 times fewer samples.
What the scores do not show
On another alignment benchmark, their 109-million-parameter text JEPA scored 0.184 against 0.154 for the evaluated Qwen2.5-72B. Parameters are adjustable values learned by a model. The score measures a particular similarity between internal representations. It does not establish that the smaller model is a better general chatbot, mathematician or programmer.
There are limits: the paper notes variation between runs and some data overlap, and its theoretical guarantees depend on its assumptions. The result is an intriguing research direction, not proof that model size has become irrelevant. It invites a more precise question: which views of the same world help machines build useful shared maps?