An AI agent can rebuild half a project in one afternoon. It can also delete a stylesheet, overwrite a config file or leave a folder in a state nobody remembers. If the only copy lives on one laptop, a broken disk or one wrong prompt can cost days of work. So the practical question is simple: what actually brings your project back?
Git and GitHub: two different jobs
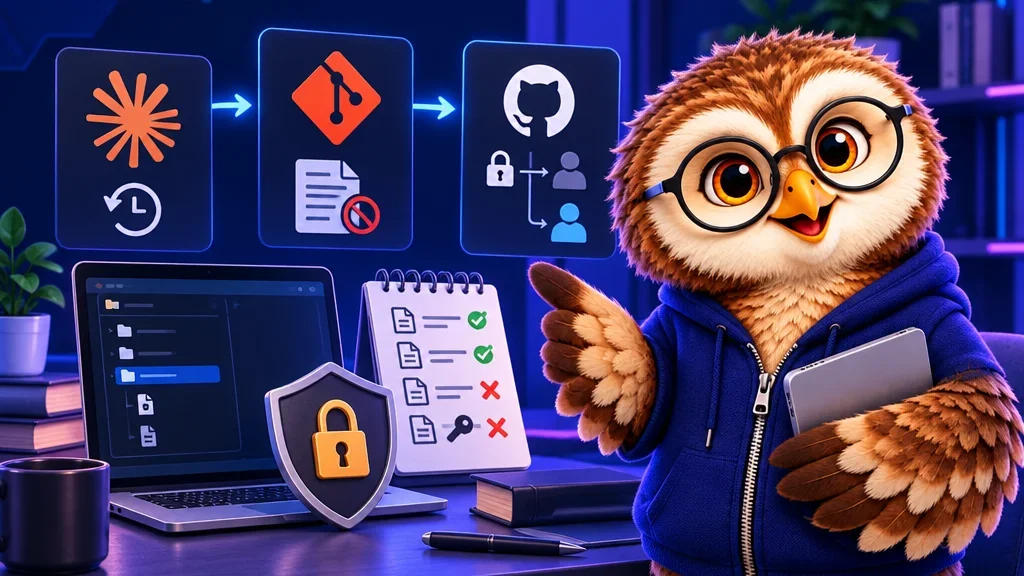
Git is version control: a program that records snapshots of your project, called commits. Each commit is a saved state you can return to later. GitHub is a hosting service for Git repositories. A repository, or repo, is the project folder together with its full history. Pushing your commits to GitHub puts a second copy of that history on a server outside your machine.
Visibility matters here. According to GitHub’s documentation, private repositories are accessible only to you, people you explicitly share access with and, for organisation repositories, certain organisation members. Public repositories are accessible to everyone on the internet. Admins can change visibility later. For a personal project or an internal agent, private is the sensible default.
What Claude Code’s checkpoints and /rewind can undo
Claude Code has its own safety net. Before each prompt that starts a turn, it captures the state of the files Claude edits with its file-editing tools. You open the rewind menu with /rewind, or by pressing Esc twice when the input is empty. There you can restore code and conversation, only the conversation, or only the code. Checkpoints are saved with the conversation, so they survive a resumed session.
The limits are documented just as clearly. A file changed only by Bash commands is not tracked. Manual edits you make outside Claude Code, and edits from other concurrent sessions, are normally not captured. Edits from most subagents are not restored. Claude Code keeps file snapshots for the 100 most recent checkpoints in a session, and by default deletes a session’s snapshots about 30 days after it last saved one.
Why commit anyway
The documentation answers this directly: checkpoints are meant for quick, session-level recovery, and it recommends continuing to use version control such as Git for commits, branches and long-term history. Rewind is an undo button for one working session. A commit pushed to GitHub is a record that exists independently of that session and of your laptop.
That is also why the two do not compete. Use rewind when the last few prompts went wrong. Pull from GitHub when the damage is bigger, when you switch computers, or when the folder itself is gone. A practical habit: commit at every stable point, and tell the agent to do so after each meaningful change or at the end of the day.
Keeping API keys out of the repository
Many projects store secrets, such as API keys or database credentials, in a .env file. That file should not end up in the repository. The usual tool is .gitignore, a file that lists paths Git should leave alone. Git’s manual is precise about its scope: it specifies intentionally untracked files to ignore, and files already tracked by Git are not affected.
Small detail. Big difference. If a .env file was committed once, adding it to .gitignore afterwards does not remove it from tracking. The manual’s fix is to remove it from the index first with git rm --cached and then add it to .gitignore. Because ignored files are never pushed, keep a separate, safe backup of your secrets.
Editor’s assessment
The fact: checkpoints and Git cover different time spans, and Claude Code’s own documentation says rewind is no substitute for version control. My inference: the risky moment is not the first commit but the first push. Before it, check the repository visibility and whether .env is truly untracked, not just listed in .gitignore. An agent can run these steps for you, but you still need to confirm the result.