Reading a long file, finding problems and producing a usable draft involves several different steps. Gemini 4 Argon is designed for that kind of sustained work. Choosing it starts with the task and the interface you will use, including how much room the model needs to produce an answer.
What work is Argon designed for?
Google announced Argon on September 30, 2026, with a focus on long, multi-step tasks. Coding, document analysis and knowledge work in areas such as law and finance are central examples. Those are the manufacturer’s capability claims; defining the task and assessing the result remain part of the workflow.
Where can you access it, and what does the API cost?
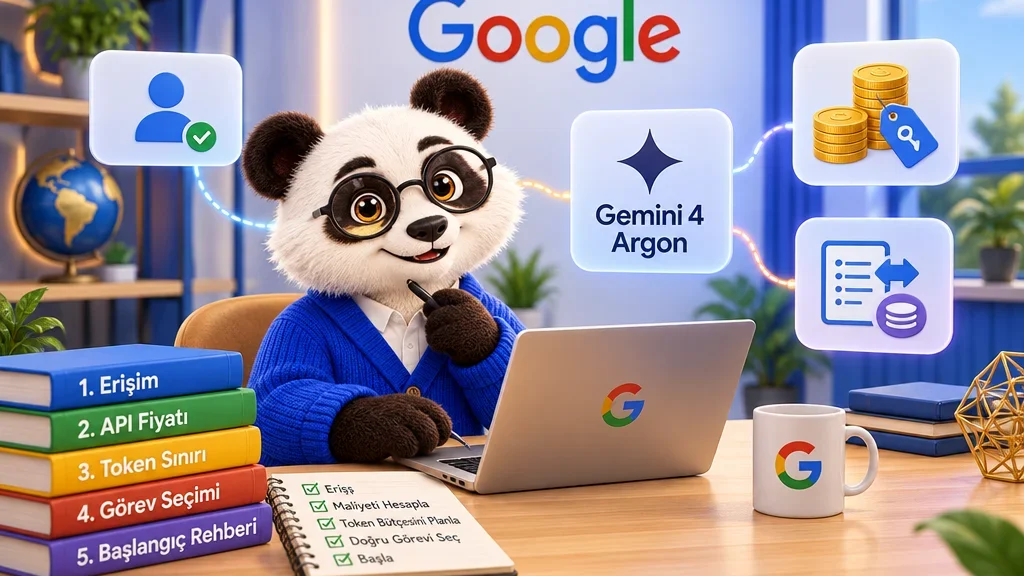
Google Cloud’s October 13 announcement lists Gemini for business on web, desktop and mobile. Developers can use the Gemini platform API, Google AI Studio and Antigravity, with gemini-4-argon as the API model ID. These routes should not be treated as one subscription package: the account and terms of the selected service apply.
The announced introductory API rates run through November 30, 2026: $2 per million input tokens and $10 per million output tokens. The stated standard rates afterward are $4 and $20 respectively. These are API processing charges, rather than the price of a chat subscription.
Why is a million tokens a shared budget?
A token is a small unit the model uses to process text, rather than a direct word count. The technical documentation specifies a unified limit of 1,048,576 tokens. Input, reasoning, tool calls and the final answer all draw from it, so a larger input leaves less room for output.
A single foreground request has a separate output limit: 65,536 tokens when streaming, or 32,768 for non-streaming direct HTTP requests. Longer generation uses the documented continuation mechanism. The total window therefore should not be confused with the answer size available in every individual request.
How should you set up the first task?
Select Argon in your chosen interface and ask for a specific result, such as inconsistencies in a document with their supporting passages. For API use, configure authentication and a current Google Gen AI SDK. Supported thinking levels are LOW, MEDIUM and HIGH; the older thinking_budget parameter and MINIMAL setting return errors.
The model card lists possible hallucinations, slow responses and timeouts. My first selection criterion would therefore be a useful, checkable finding rather than the longest possible answer. Define the output and compare it with the original document. The shared budget reinforces that choice: unnecessary files consume space that could otherwise support reasoning and the response.