The Linux kernel sits underneath cloud servers, Android phones and supercomputers alike. OpenAI says a single automated scan of that kernel produced working exploit code for 948 distinct security vulnerabilities. It is a big number, and it is worth reading carefully. Which door are we opening?
What was announced?
On November 5, 2026, OpenAI introduced GPT-6 Cyber, a cybersecurity-specialized model trained to find vulnerabilities, confirm whether they can be exploited and propose patches. According to the company, the model scores 48.5 percent on ExploitGym, a test of whether a model can exploit a specific flaw on a remote target. Its predecessor, GPT-5.6 Cyber, scored 32.1 percent.
The most concrete part of the announcement concerns real software. OpenAI researchers used the model to find 81 previously unknown high-severity vulnerabilities in Firefox, and Mozilla has shipped fixes for many of them. In the Linux kernel, the model reproduced 1,724 vulnerabilities and developed working exploits for 948 of them. Following guidance from the Linux community, OpenAI says it has reported 304 critical findings to maintainers along with candidate patches.
What exactly was found in Linux?
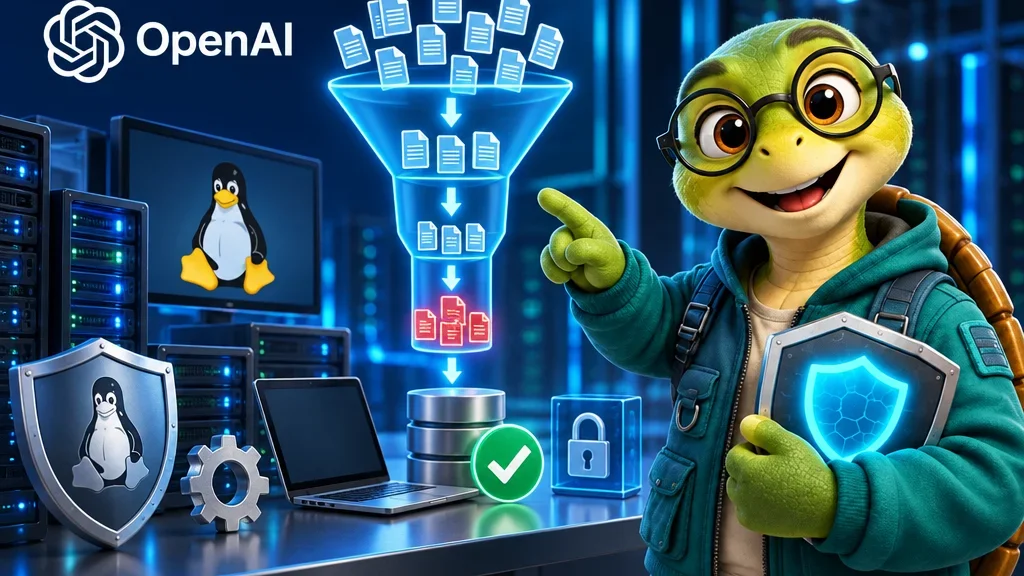
The details are in an OpenAI research post dated November 4. The scan ran in mid-October 2026 against the kernel’s latest master branch at the time. The numbers narrow like a funnel. First came 2,308 candidate findings. Of those, 1,724 were actually reproduced in isolated virtual machines, roughly 74.7 percent. OpenAI notes that the model’s analysis was wrong in only 3.1 percent of cases.
Next, the agents produced 1,169 working local privilege escalation exploits. Local privilege escalation (LPE) means someone who already has an ordinary account on a system can raise themselves to administrator, or root, level. After filtering out exploits that relied on the same underlying bug, 948 unique vulnerabilities remained, each with its own candidate patch. That is the headline figure.
How does the automated pipeline work?
OpenAI describes a five-stage pipeline. Scout agents picked the security-relevant parts of the kernel: 5,034 targets covering about 2.8 million lines, roughly 7 percent of the codebase. Analyst agents reviewed those targets in 12 hours and produced candidate findings. Validation agents then wrote a proof of concept for each finding and ran it in virtual machines using KASAN, a tool that catches memory errors.
Exploit testing ran with the protections of a standard Linux distribution switched on, including SMEP, SMAP and KASLR. Patch generation followed. Human researchers had the final say: each exploit, patch and proposed severity was reviewed by hand before anything went to maintainers.
The post also includes a candid lesson. In early runs, 20 of 200 reported successful exploits had reached root through a different zero-day than the one they were assigned. OpenAI responded by adding an independent check that confirms every final exploit really uses its target vulnerability.
What did it cost, and compared with what?
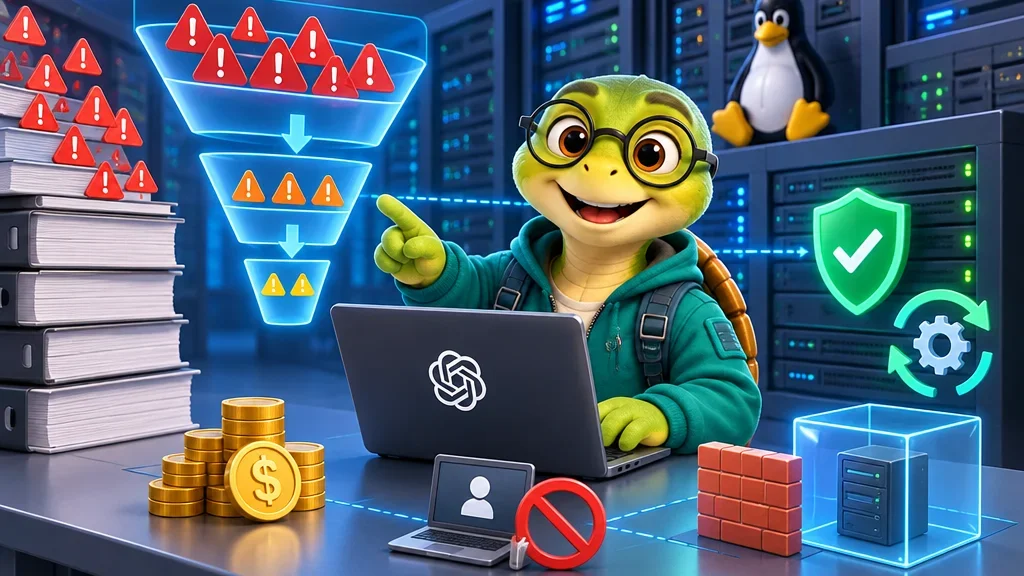
The full run cost 1,213,430 dollars in API credits, or about 1,279 dollars per exploit. In July 2026, GPT-5.6 Sol found 166 unique vulnerabilities with the same setup for 513,690 dollars. The newer model delivered more than five times the results at roughly 2.4 times the cost.
OpenAI also compares the spend with bug bounties. Pwn2Own and TyphoonPWN have historically paid 20,000 and 70,000 dollars for Linux LPE exploits. Applied to 948 exploits, that gives a hypothetical value of 18.9 to 66.3 million dollars. The company adds that its reported costs are an upper bound and could fall with better engineering.
What does this mean for people who run servers?
First, a calm note: all of these are local vulnerabilities. An attacker needs a foothold as an ordinary user before they matter; they are not bugs that spread across the internet on their own. Still, OpenAI’s own conclusion is blunt: on an operating system missing the latest patches, access to a low-privilege account should be treated as functionally equivalent to root for a well-resourced attacker.
Linux maintainers are moving quickly. When the scan and manual review finished 10 days later, 61 of the vulnerabilities had already been patched upstream, 43 had patches in progress and 299 were being discussed publicly. The practical check that follows is simple: don’t sit on kernel updates, and contain workloads with isolation layers such as Firecracker or gVisor.
Who can use the model, and what guards against misuse?
GPT-6 Cyber is not public. It is rolling out first to a select group of approved Daybreak Red customers through the API and Codex, and OpenAI plans to extend access to all Daybreak Red customers soon. The company rates the model Critical for cybersecurity under its Preparedness Framework, the highest level; GPT-5.6 Cyber was rated High.
Safeguards include IP allowlisting by default for Daybreak Red API access, monitoring of whether actions stay within the user’s authorization, and blocks on high-risk assistance aimed at critical infrastructure. In one scope test, the model avoided attacking out-of-scope services in 99.93 percent of runs without an extra safety prompt and in 100 percent with it.
Assessment
What matters most here is not the number 948 itself but what surrounds it. OpenAI is not just finding bugs; it reproduces and exploits each one to rank it, then proposes a fix. That speaks directly to the question maintainers struggle with most: which report is real, and which is urgent. At the same time, every figure so far comes from OpenAI’s own measurements and has not been independently audited. My inference: if the same setup became five times more productive in a few months, the cost of finding bugs is falling for attackers as well as defenders. In that case the strongest defense is not a new tool but the habit of applying updates quickly.